Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD

Senior Data Engineer
Competenze
Consulta i miei servizi
Senior Data Engineer
Capgemini • Full time
Sep 2018 - Present • 8 yrs 1 mo
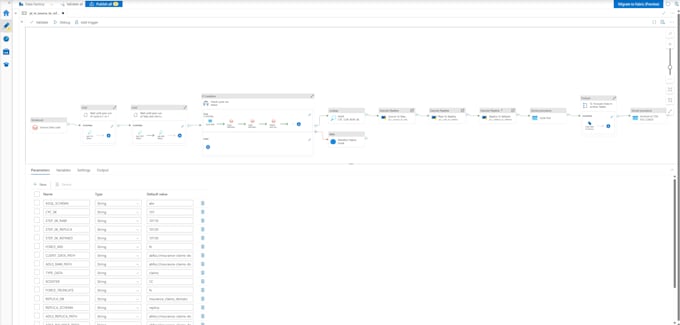
Project: Guidewire CDA Data Ingestion ▪ Built a near-real-time ETL pipeline on Azure Data Factory and Azure Databricks (PySpark/Spark SQL) to ingest Guidewire CDA data from AWS S3 into ADLS Gen2 using Medallion Architecture (Bronze, Silver, Gold), reducing data latency from daily batch to hourly. ▪ Implemented a custom ABC (Audit, Balance & Control) framework on Azure SQL Server to track every ETL pipeline run, enabling automatic failure recovery, preventing overlapping runs, and eliminating manual intervention. ▪ Governed Delta Lake tables in Databricks Unity Catalog with SCD Type 2 MERGE and MD5 hash-based change detection, ensuring full auditability and zero data loss across all data pipeline layers. ▪ Built an automated data pipeline reconciliation framework with Azure Logic Apps alerting on failures before bad data reached downstream Power BI reports. ▪ Delivered CI/CD automation via Azure DevOps for ADF and Databricks across dev, staging, and production; authored a formal production runbook for handoff. Project: IIG DataStage Modernization ▪ Designed and built ETL/ELT data pipelines in AWS Glue to migrate 300+ legacy DataStage jobs to AWS Cloud, improving job runtime by 40% and reducing operational costs by 25%. ▪ Built PySpark and Apache Spark scripts for data extraction, cleansing, transformation, and loading into Amazon S3 and Amazon Redshift across source-to-target data pipeline layers. ▪ Implemented AWS Lambda and Step Functions for workflow orchestration, enabling fault-tolerant and dependency-aware ETL job execution. ▪ Optimized Apache Spark jobs using performance tuning - broadcasting, predicate pushdown, and caching - reducing overall pipeline execution time by 30%. ▪ Established proactive monitoring and alerting using AWS CloudWatch metrics and Glue logs, cutting issue detection time by 50%. ▪ Maintained technical documentation in Confluence/Jira and managed code versioning in GitHub across the full data pipeline migration lifecycle.
