Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD

Level 2
AI SYNTHETIC DATA & MODEL BENCHMARKING
THE PROBLEM
Poor training data can cause hallucinations, inconsistent outputs, and costly production issues. Manual niche-data labeling is slow and expensive.
THE SOLUTION
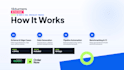
We create production-ready synthetic datasets with realistic edge cases and automated evaluation pipelines to test model accuracy, latency, and reliability.
WHAT WE DELIVER
WHY TKTURNERS
Specialized AI engineering focused on high-quality datasets, structured generation, and reliable model evaluation.
FAST DELIVERY
Get validated datasets and benchmark pipelines ready for fine-tuning or production evaluation.
FREE DATA REVIEW
Message before ordering for a free data strategy & schema review.
Senior Software Engineer
Level 2
Lingue
Why should I message you before ordering?
Messaging beforehand allows us to review your data schema, domain requirements, and evaluation targets to match the right package and prevent delivery delays.
What is synthetic training data and how is it used?
Synthetic training data is artificially generated data that mimics real-world distributions. It enables fine-tuning and testing AI models without privacy risks or manual labeling costs.
What data formats do you support?
We deliver data in JSONL, CSV, Parquet, JSON, and standard Hugging Face dataset formats optimized for fine-tuning OpenAI, Anthropic, or open-source models.
How do you ensure the synthetic data is high quality?
We use schema constraints, semantic deduplication, statistical distribution checks, and automated validation rules to eliminate hallucinations and formatting errors.
What is included in the model evaluation pipeline?
The pipeline includes automated benchmark testing, accuracy scoring, latency tracking, LLM-as-a-judge evaluation, and regression testing reports.
Are API usage and third-party model costs included?
No, API usage costs (OpenAI, Anthropic, or cloud compute) are billed directly to your account. We assist with key configuration and budget optimization.
What access or information do you need to get started?
We need your target schema, sample data examples (if available), business domain rules, and the evaluation criteria or metrics you want to benchmark.
How is my proprietary business data kept private?
We sign standard non-disclosure agreements, never store your sensitive inputs permanently, and generate fully anonymized, privacy-compliant datasets.
How do revisions work for dataset generation?
Revisions include fine-tuning dataset distribution, adjusting edge cases, refining prompt templates, or re-running specific evaluation metrics.
Do you provide ongoing pipeline maintenance?
Yes, we offer ongoing maintenance and dataset expansion through custom milestones or monthly support packages.


