Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD


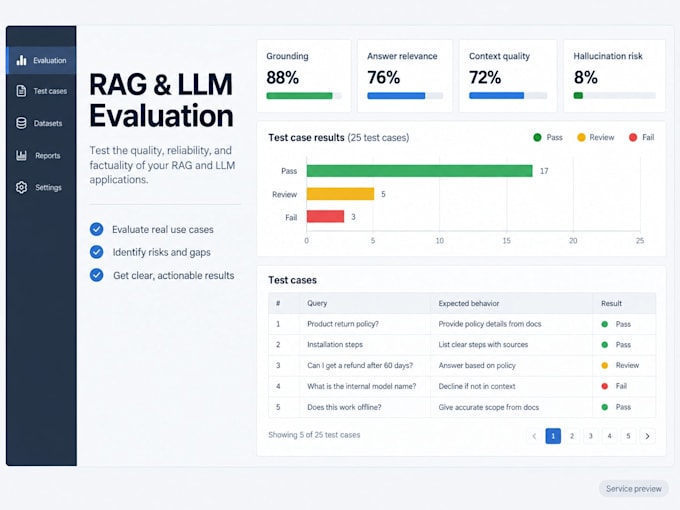
Is your RAG or LLM application producing unsupported, irrelevant or inconsistent answers? I will evaluate its behavior and provide evidence-based recommendations for improvement.
I can assess:
Answer relevance, clarity and completeness
Grounding in retrieved context
Hallucinations and unsupported claims
Retrieval quality and source usefulness
Citation consistency
Failure patterns and fallback behavior
Latency and cost indicators when data is available
Chunking, context and model configuration decisions
Depending on the package, I will review supplied test cases, create a structured evaluation set, analyze retrieval and generation failures, and use automated metrics when they are technically appropriate. You will receive a clear report separating observations, evidence, limitations and prioritized recommendations.
Please provide access to a safe test environment or exported application results, retrieved contexts, expected answers when available, and a description of the intended users and use case. Remove API keys, production credentials and private customer data.
This Gig evaluates an existing system. Implementing major changes, rebuilding the RAG pipeline, production deployment a
Python Backend Applied AI Developer
Lingue
Q: What counts as one evaluation case?
A: One case includes a user question, the generated answer and the retrieved context or sources used to produce it. Expected or reference answers are helpful but not always required.
Q: Do you need access to my production system?
A: No. I prefer a safe test environment, exported results or a reproducible local version. Please remove API keys, production credentials, personal information and confidential customer data before sharing anything.
Q: Which evaluation metrics do you use?
A: Metrics depend on the application and available data. Evaluation may cover answer relevance, context relevance, faithfulness, source grounding, retrieval quality, hallucination patterns, latency and cost indicators. Automated tools may include RAGAS or equivalent methods when appropriate.
Q: Will you implement the recommended improvements?
A: This Gig focuses on evaluation and recommendations. Small agreed adjustments may be offered separately, while major pipeline changes, new features and deployment require a custom offer.
Q: Can you guarantee that the evaluation will eliminate hallucinations?
A: No responsible evaluator can guarantee that an LLM will never hallucinate. I will identify observed failure patterns, measure them where possible and recommend practical ways to reduce their frequency and impact.