Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD
AI Data Engineer, RAG Pipelines, PDF to Markdown, Local LLMs
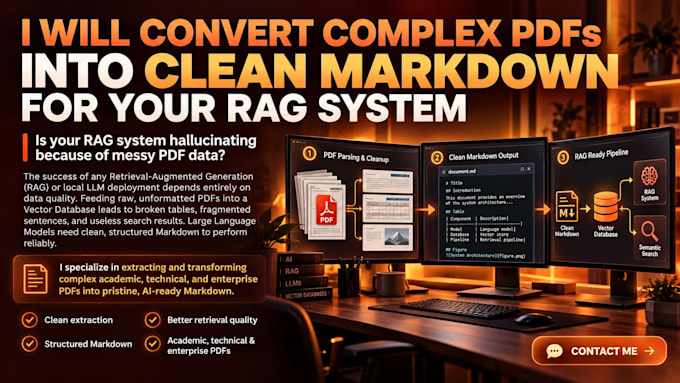
Is your RAG system hallucinating because of messy PDF data?
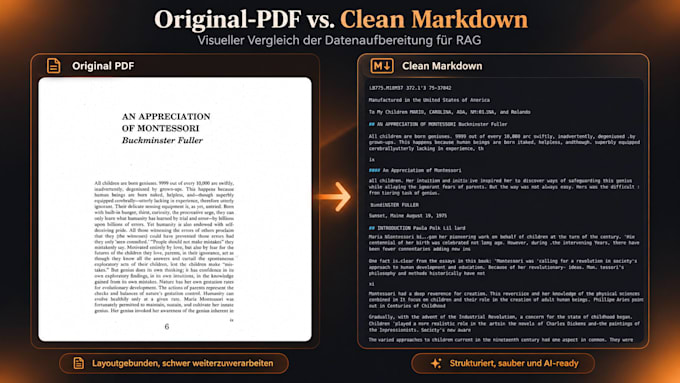
The success of any RAG or local LLM deployment depends entirely on data quality. Feeding raw PDFs into a Vector Database leads to broken tables and useless search results. LLMs need clean, structured Markdown to perform reliably.
I specialize in transforming complex academic, technical, and enterprise PDFs into pristine, AI-ready Markdown.
What I Deliver:
The Privacy-First Guarantee: As an enterprise AI architect, I process highly sensitive data on local, high-performance edge hardware. Your confidential manuals and reports are NEVER sent to cloud APIs. 100% offline, 100% GDPR-compliant.
Stop wasting developer hours on manual formatting. I will deliver the clean data foundation your AI requires.
Please contact me before ordering to discuss your documents.

Are my confidential documents sent to the cloud?
Absolutely not. I guarantee a strict "Zero-Cloud" policy. All PDFs are processed 100% locally on my offline edge hardware. No OpenAI or third-party APIs are used, ensuring total data sovereignty and strict GDPR compliance.
Can you extract data tables and code blocks correctly?
Yes. Unlike basic extraction tools, my pipeline accurately parses data tables and code snippets, converting them natively into clean, structured Markdown formatting that your Vector Database and LLMs can perfectly understand.
What if my PDF has a complex multi-column layout?
Multi-column layouts are handled smoothly. The pipeline uses advanced layout recognition to ensure the text flows in the correct, logical reading order, completely avoiding the broken, mid-sentence line breaks typical of standard PDF converters.
What document languages do you process?
I specialize in processing and manually quality-assuring documents in English and German. Restricting the service to these languages ensures I can personally verify the structural integrity and formatting of the final Markdown output before delivery.
I have thousands of pages. Can you handle massive enterprise archives?
Yes. The 500-page Premium package is just a starting point. For massive corporate archives or highly specific OCR needs (scanned documents), please message me directly. I will engineer a custom, automated ETL pipeline specifically for your document corpus.