Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD
data analyst
New seller pricing: the first 5 orders are discounted while I build my review history.
A model you can defend, not just a score you have to trust.
What you get
- Honest validation: stratified or time-based split, reported as it is
- Feature engineering grounded in your business: RFM, behavioural, transactional, time-based
- Models compared on the same split, so the choice is justified rather than assumed
- Class imbalance handled properly: SMOTE, class weights or threshold tuning
- Feature importance ranked and translated into business terms
- A summary a non-technical stakeholder can read: AUC, lift, precision at K
Tools: Python (pandas, scikit-learn, NumPy, LightGBM), SQL
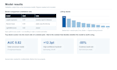
Track record: churn and recall models at AUC 0.80, order conversion prediction across 47 features at AUC 0.82, and a lead scoring model that lifted the high-confidence handover rate from 7.7% to 20%.
What I need: a target column, a few thousand rows of history, and the decision the score will drive. If your data is still messy, either I clean it inside the Premium tier, or you order my data cleaning Gig first.
Message me with your row count and target column, and I will confirm scope before you order.
Linguaggio di programmazione:
Python
•
SQL
Framework:
Scikit-learn
•
Panda
Strumenti:
Quaderno jupyter
•
Excel
Which algorithm will you use?
By problem, not habit: regularized linear models as the baseline, tree ensembles (LightGBM, scikit-learn), SVM or k-NN for small non-linear data, clustering for segments, ranking for ordered lists. Chosen on validation, never on fashion - and I tell you what I rejected.
What accuracy can I expect?
I will not promise a number before I see the data, and anyone who does is guessing. What I commit to is honest validation and a clear report of where the model fails. For reference, my own projects landed at AUC 0.80 to 0.82 on churn and conversion problems.
My dataset is small or imbalanced. Can you still work with it?
Usually yes. Imbalance is handled with SMOTE, class weights or threshold tuning rather than ignored. Small data is a real limit though - if there are too few positive cases I will tell you that plainly before you order, instead of delivering a model that cannot be trusted.
Will I get the code?
Yes on every package. You get a notebook or script you can rerun plus the final feature list. The Premium tier adds a production script, written documentation and a handover call.
Can you deploy the model to production for me?
I do not do cloud deployment or API integration, and I would rather say that up front than take the order and disappoint you. What you get is a model and a script that is ready for your engineering team to deploy.
My data is sensitive. How do you handle it?
Send a masked extract or a small sample if you prefer. I only ask for the columns the model actually needs, I do not share your files with anyone, and I delete the working copy once the order is complete.


