Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD
Are you struggling with messy, unorganised data? Clean data is essential for reliable business decisions and accurate predictive models.
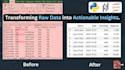
As a Python Data Scientist, I transform raw datasets into clean, structured, and actionable insights.
What I Offer: Data Cleaning: Handle missing values, remove duplicates, correct data types, and identify outliers. Data Transformation: Merge files, reshape datasets, and organise features. Exploratory Data Analysis (EDA): Discover trends, patterns, and anomalies. Data Visualisation: Create insightful charts, histograms, scatter plots, and heatmaps.
Tools & Technologies: Python, Pandas, NumPy, Matplotlib, Seaborn, SciPy, Jupyter Notebook, MongoDB, SQL. DuckDB and JSON.
Why Choose Me? Clean, professional, well-documented code. Fast delivery and regular progress updates. Focus on data accuracy, privacy, and security.
Whether you need basic data cleaning or in-depth analysis, I'm ready to help transform your data into valuable insights.
Message me before placing an order to discuss your dataset, file format, requirements, and project goals. Let's make your data analysis-ready!



What Python libraries do you use for data cleaning and EDA?
I primarily use Pandas and NumPy for efficient data manipulation and cleaning. For exploratory data analysis and visualisation, I utilise Matplotlib, Seaborn, and Plotly to generate clear, insightful charts.
What formats of data files can you work with?
I can work with almost any standard data format, including CSV, Excel (.xlsx, .xls), JSON, SQL databases, TXT, and Parquet files.
What is included in your "Data Cleaning" process?
The cleaning process typically involves handling missing or null values, removing duplicate records, fixing inconsistent data formatting, correcting data types, filtering out outliers, and structuring the data for seamless analysis.
Will I receive the source code, or just the final cleaned data?
You will receive both. I will provide the fully structured, clean dataset in your preferred format (e.g., CSV, Excel) along with the complete, well-documented Jupyter Notebook (.ipynb) containing the Python source code.
Can you handle large datasets or Big Data?
Yes, I can handle moderately large datasets within standard Python environments. If you have exceptionally large files (gigabytes of data), please message me before ordering so we can discuss optimised solutions like Dask or chunk processing.
What if my data contains sensitive or confidential information?
My first concern is data privacy. If necessary, I will gladly sign a Non-Disclosure Agreement (NDA). Alternatively, before sending me the dataset, you might mask or anonymise any sensitive columns (such as credit card numbers or names).
Can you extract or fetch data directly from MongoDB and DuckDB databases?
Yes. I can connect to your MongoDB collections to export JSON data, or query your DuckDB databases to fetch and process data directly. I can export the final, cleaned results into standard formats like CSV, Excel, or Parquet.


