Io distribuirò e metterò a punto un llm privato self-hosted sul tuo server GPU

S
stchopko
S
stchopko
Stepan C.
Alcune informazioni sono state tradotte automaticamente.

Informazioni su questo servizio

Traduzione automatica.

Vuoi un’IA stile ChatGPT che funzioni sul tuo hardware, con zero dati inviati a terze parti? Imposterò tutto e lo renderò veloce.


La maggior parte delle configurazioni installa solo un runner con impostazioni predefinite e lascia sul tavolo prestazioni 2-3x superiori. Io effettuo benchmark e ottimizzo per la tua GPU e RAM esatte. Risultati reali dal mio server (Tesla P100 16GB + EPYC):

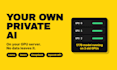
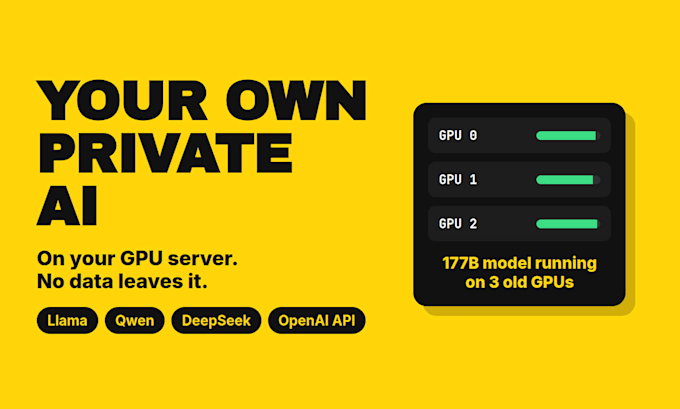
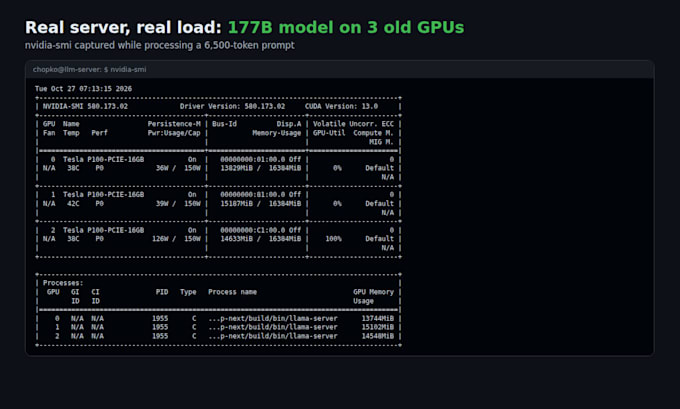
  • modello MoE da 177B parametri su tre vecchie GPU da 16GB a 13,5 token al secondo
  • elaborazione prompt 3,4x più veloce (75 a 254 token al secondo) ottimizzando le dimensioni dei batch
  • modello di coding da 80B a 30 token al secondo su due GPU più vecchie
  • la giusta quantizzazione per la tua generazione di GPU

Cosa ottieni:

  • server llama.cpp con API compatibile OpenAI
  • interfaccia chat web
  • scelta del modello in base al tuo hardware e al caso d’uso
  • servizio auto-avvio e accesso remoto sicuro
  • Rapporto di benchmark: a che velocità vai e perché

Inviami la tua GPU, RAM e cosa vuoi far fare all’IA, e ti dirò cosa è realistico prima che tu ordini.

Scopri di più su Stepan C.

Stepan C.

PHP Developer and Self Hosted LLM Engineer

  • DaUcraina
  • Membro damag 2021
  • Lingue

    Ucraino, Inglese
Backend developer with 9 years of commercial PHP (Symfony, Laravel, legacy code), including 6 years as Senior PHP Developer at an Irish software company, and hands-on experience running large language models on my own hardware. I fix and upgrade PHP sites that broke after a PHP 8.x update, migrate projects to modern Linux servers, and deploy private, self-hosted LLMs that run on your own GPU - no data leaves your server. I don't guess: I find the root cause, fix it, and tell you what was wrong. Clear written communication, fast replies.

Traduzione automatica.