Sfoglia categorie
Esplora
Fiverr Pro
Italiano
$
USD

Vetted Pro
Level 1


Zlatin S selezionato dal team Fiverr Pro per la sua esperienza.
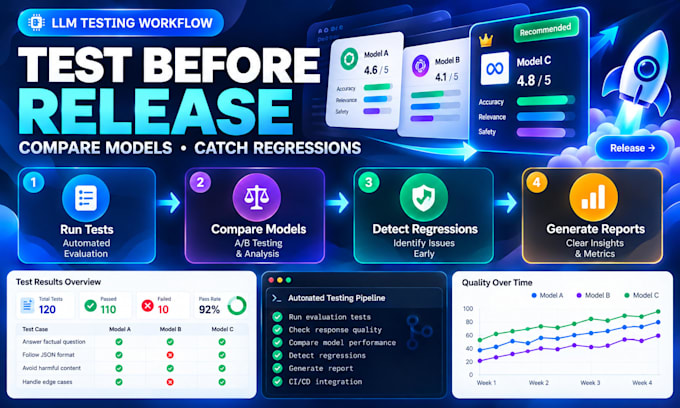
Your AI app works today. Will it still work after a model or prompt update?
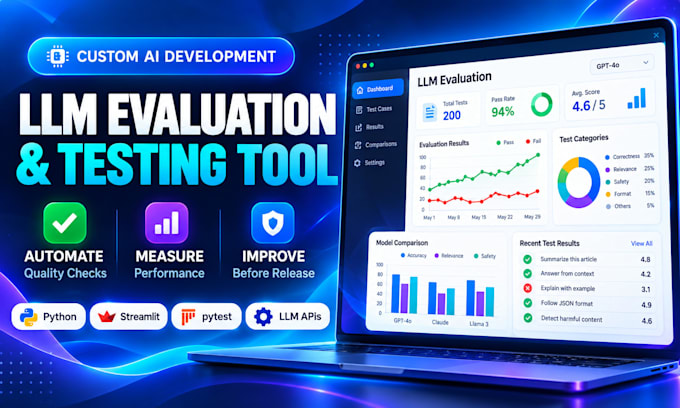
I build Python-based LLM evaluation tools that help teams detect failures, track response quality, and catch regressions before release.
WHAT I BUILD
PACKAGES
Basic: 25 test cases, 2 checks, and a simple results dashboard.
Standard: 75 test cases, 3 criteria, detailed analysis dashboard.
Premium: 150 test cases, 4 criteria, comparison and CI automation.
YOU RECEIVE
Python source code, evaluation test files, result exports, setup instructions and a demonstration.
Scope: One agreed English-language workflow. Model API charges, hosting, fine-tuning and ongoing monitoring are excluded. No evaluation system guarantees zero hallucinations.
Please message me before ordering to confirm your API, test data and acceptance criteria.
Vetted Pro
Senior AI and Full Stack Engineer
Level 1
Zlatin S fa parte del catalogo di Fiverr Pro ed è stato selezionato da un team di Fiverr Pro per le sue capacità e competenze.
Selezionato per
Sviluppo AI
Lingue
What types of AI applications can you evaluate?
I can build tests for text-based LLM APIs, chatbots, and similar AI applications. More complex agent or multimodal workflows require a custom scope.
Which LLM providers do you support?
I support OpenAI-compatible endpoints and other providers with accessible APIs, subject to confirming their integration requirements before the project.
Can you detect AI hallucinations?
I can implement groundedness and reference-based checks where suitable data is available. These checks help identify potential hallucinations but cannot guarantee perfect detection.
Can you test a RAG chatbot?
Yes, within an agreed response-evaluation scope. Advanced document retrieval testing, citation verification, and end-to-end RAG testing may require a custom offer.
Will I receive the complete source code?
Yes. I provide the agreed Python source code, test cases, evaluation reports, and setup instructions.
Can I run the tests after delivery?
Yes. The framework is designed for repeated execution using your configured API access and local environment.
Are API usage and hosting included?
No. Third-party model usage, API credits, cloud hosting, and ongoing monitoring are not included in the package price.
What is included in a revision?
A revision covers corrections and adjustments within the agreed specifications. New models, integrations, or major features require a separate quote.